AI Infrastructure
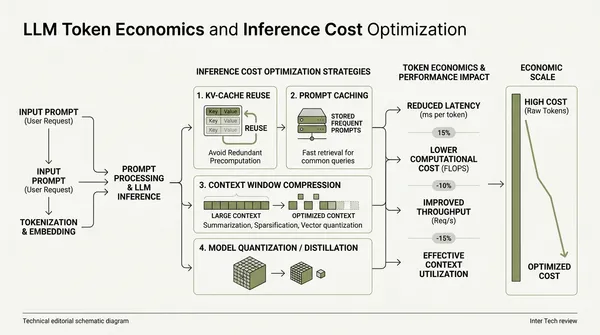
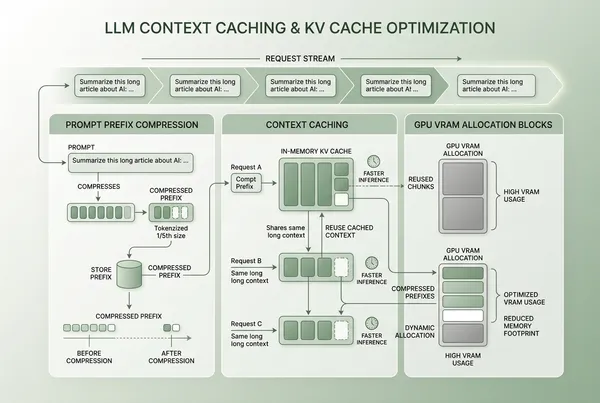
Slashing Inference Costs: Context Caching, Prompt Compression, and KV-Cache Reuse
How frontier caching architectures like vLLM PagedAttention, Anthropic Prompt Caching, and Gemini Context Caching drop LLM latency by 80% and inference bills by 75%.
October 8, 2026 · 7 min read